Google generally finds job listings in the same way it finds any other page: it follows links from pages it already knows, reads sitemaps you provide, and uses other discovery signals. It may then crawl each URL and decide whether to index it. Publishing a job page does not mean Google will find it straight away, and finding a page does not mean Google will show it.
It helps to separate five outcomes that people often treat as one: the page is published, Google has discovered it, Google has crawled it, Google has indexed it, and it appears in search results.
This guide explains how Google finds job listings and what happens at each stage, why some vacancies never appear, and how to check what is going on. Google does not guarantee that any page will be crawled, indexed or served, so the aim is to remove avoidable obstacles, not to promise a result.
How Google Finds Job Listings Through Links and Sitemaps
Google describes this first step as URL discovery. According to its guide to how Google Search works, some pages are already known, others are found when Google follows a link from a known page, and others are found when a site owner submits a sitemap. For a company website, the most common routes are:
- Internal links from your careers page to each open vacancy.
- Links from category or location pages that group your jobs.
- An XML sitemap that lists your job URLs.
- Links from other websites, such as a job board or a social profile.
- URLs Google already knows from earlier visits.
A typical path looks like this: your homepage links to the careers page, the careers page lists open positions, and each position links to its own job detail page. If a vacancy sits outside that chain, Google may never meet it. A sitemap can help, but a page should not depend on a sitemap alone. Every job you want found should be reachable through ordinary links as well.
What Happens When Google Crawls a Job Page
Once Google knows a URL, it may visit it. Googlebot, Google’s crawler, requests the page, your server responds, and Google processes what comes back. Google also renders the page and runs the JavaScript it finds, using a recent version of Chrome, because many sites load content with scripts. If your job description only appears after a script that Google cannot run, Google may not see it.
Crawling can be held back by server problems, network issues, robots.txt rules, pages that need a login, or Google’s own scheduling. Google says it does not crawl every page it discovers. Crawling is also separate from indexing: a page can be crawled and still not be indexed.
How Google Understands the Job Listing Content
After crawling, Google tries to work out what the page is about. For a vacancy, the useful signals are on the page itself:
- The job title, in the page heading and the page title.
- The employer.
- The job description and the main responsibilities.
- The location or remote working arrangement.
- The employment type.
- Headings that give the page a clear structure.
- Links to and from the rest of your site.
- Structured data, where the page includes it.
The visible content should be accurate, specific and consistent with everything else on the page. Structured data is introduced later in this guide, and the details belong to a separate article.
The Difference Between Crawling, Indexing and Ranking
These terms describe different outcomes, and one does not guarantee the next.
| Stage | What it means | What can go wrong |
|---|---|---|
| Published | The page exists on your website | Nothing links to it, or it is hidden from visitors |
| Discovered | Google knows the URL | Google may not have found it yet |
| Crawled | Google has requested and processed the page | Blocked, slow, broken or needs a login |
| Indexed | Google has stored the page in its index | Duplicate, noindex, low value or not selected |
| Ranked or displayed | The page may appear for relevant searches | Many other pages compete for the same searches |
A crawled page may not be indexed, and an indexed page may not appear prominently. Google also says that indexing is not guaranteed even when a page follows its guidelines.
Why Some Job Listings Are Not Indexed
When a vacancy does not appear, one of these causes is often behind it:
- No link from the careers page, so the page is orphaned.
- A robots.txt rule that blocks the URL.
- A noindex directive on the page.
- An error response, or an unexpected redirect.
- A canonical tag that points to a different URL.
- Thin or heavily duplicated content.
- A job that is no longer available.
- A page that needs a login.
- A page Google has not yet crawled.
- A page that does not meet Google’s indexing criteria.
Not every exclusion is a fault. Google may choose not to index a page that is a duplicate or adds little, and it can take time for a new URL to be processed. The goal is to rule out problems you can fix, not to force every URL into the index.
Why Internal Linking Matters for Job Pages
A sensible structure keeps every vacancy a short click path from the homepage: homepage, careers page, job category or listing page, then the individual job. Use clear navigation and descriptive link text, make sure links are ordinary crawlable links rather than controls that only work after a search, and avoid orphaned job pages that nothing links to.
Link your open roles from the main careers page and keep that page useful even when few roles are open. Our guide to building a professional careers page in WordPress covers the page itself, and adding job listings to a WordPress website covers publishing the vacancies that sit beneath it.
How XML Sitemaps Help Google Discover Job Pages
A sitemap is a file that lists the pages on your site and gives search engines information about them. Google’s documentation on what a sitemap is explains that sitemaps help search engines crawl a site more efficiently, and that you might benefit from one if your site is large, new or has few external links. It also says a small, well-linked site may not need one.
For job pages, keep a few points in mind:
- A sitemap helps discovery. It is not a ranking factor and it does not guarantee indexing.
- List the canonical URL of each vacancy, not duplicates or redirected addresses.
- Keep entries accurate, and update the sitemap as jobs are added, changed or removed.
- Do not list jobs that are closed or pages that you have set to noindex.
How to Check Job Listing Discovery in Google Search Console
Google Search Console shows what Google knows about your pages. A practical check for one vacancy looks like this, using Google’s help page for the URL Inspection tool:
- Open Search Console and choose the correct website property.
- Paste the full job URL into the inspection bar at the top. The URL must belong to that property.
- Read the indexing result, which describes Google’s indexed version of the page, not the live page.
- Check whether Google found and crawled the URL, and which canonical it selected.
- If you have fixed something, use the live test to see whether the current page looks indexable.
- Look at the sitemap and page indexing reports for patterns across many job pages.
- If appropriate, request indexing for the URL.
Requesting indexing asks Google to crawl a URL. It does not guarantee indexing, and there is a daily limit on inspection requests. Menu names and report labels change from time to time, so follow the wording in the current Search Console interface.
How JobPosting Structured Data Fits Into Discovery
JobPosting structured data describes the details of a vacancy in a standard format. Google’s job posting documentation explains how it can make a page eligible for job search experiences. It does not replace the earlier steps. Discovery helps Google find the page, crawling lets it read the page, indexing concerns whether the page is stored, and structured data communicates the job’s details. Eligibility for a feature is not a promise of display.
The markup must also match what visitors can see on the page. The details of how it works are covered separately, so here the point is only that structured data is one input among several.
How WordPress Job Listing Websites Can Support Discoverability
WordPress does not automatically provide every technical requirement, because themes, plugins and settings all affect the result. Check that each vacancy has its own URL, that the careers page links to open roles, that canonical URLs are correct, that pages you want found are not set to noindex, and that your sitemap is configured.
Avoid empty or duplicate job pages, keep vacancy details accurate, and test the pages on a phone. If you are weighing options, the comparison of a WordPress job board and a recruitment plugin and our overview of making WordPress job listings SEO-friendly are useful companions.
Where CMAA Recruit Fits
CMAA Recruit is a WordPress recruitment plugin for publishing jobs on your own website. In the current Free plugin, each job is a public post type with its own address under a jobs path and a jobs listing page, so every vacancy has a single URL that can be linked from your careers page. You can read more in CMAA Recruit as a WordPress ATS.
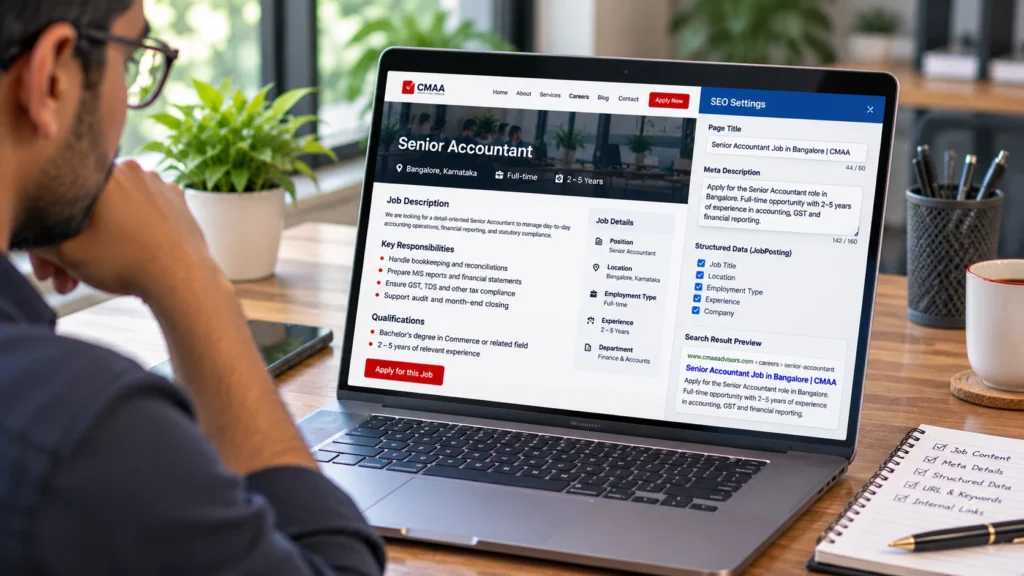
The Advanced Job Builder includes SEO fields for each job: an SEO title, a meta description, a canonical URL option, social sharing tags and a noindex checkbox. On single job pages the plugin outputs JobPosting and BreadcrumbList structured data built from the job’s own details, and it includes a validThrough date when you set an expiry date. When the expiry date passes, the application form closes.
A few limits are worth knowing. The plugin does not create its own sitemap, so whether job pages appear in a sitemap depends on WordPress core or your SEO plugin, and you should check yours. As far as the current plugin code shows, nothing unpublishes or noindexes a job page when it expires, so decide how to handle closed vacancies yourself. And no plugin can guarantee indexing, rankings or Google for Jobs placement.
Make your WordPress recruitment website easier to manage
Explore how CMAA Recruit supports structured job publishing and application management through WordPress.
Frequently Asked Questions
How long does Google take to find a new job listing?
There is no fixed time. It can be quick for a site that Google visits often and slow for a new or poorly linked one. Links from your careers page and an accurate sitemap make discovery more likely, but neither sets a timeline.
Does submitting a sitemap guarantee that Google will index a job page?
No. A sitemap helps Google discover URLs. Google still decides whether to crawl and index each page, and indexing is not guaranteed.
How can I check whether Google has crawled my job listing?
Use the URL Inspection tool in Search Console for that URL. It shows Google’s indexed version of the page, any crawl and indexing information, and the canonical Google selected.
Why is my job listing not appearing in Google?
It may not be linked, may be blocked or set to noindex, may redirect or return an error, may be a duplicate, or may simply not have been crawled yet. Inspect the URL in Search Console to narrow it down, and remember that Google may choose not to index a page.
Does JobPosting schema help Google discover job pages?
Not directly. Discovery comes from links, sitemaps and other signals. JobPosting structured data describes the vacancy once Google has the page, and it can make the page eligible for job search features.
Should every job vacancy have its own URL?
Usually yes. A dedicated page gives each vacancy a stable address that can be linked, crawled and inspected, and it is what Google’s job posting guidance expects for structured data.
Final Takeaway
Make every job page reachable through internal links and, where useful, a sitemap. Make sure Google can access it, give it useful and accurate content, check indexing in Search Console, and keep vacancy details current. Do those things consistently and you remove the common obstacles, though no step can promise that Google will index or show a particular job.
Compare WordPress recruitment features for your website
Compare the Free and Pro capabilities against your actual job publishing and recruitment requirements.
About CMAA Softwares
CMAA Softwares builds practical software for SMEs and professional firms, grown out of problems solved first inside CMAA Advisors' own payroll, compliance, and recruitment desks. CMAA Recruit is our recruitment ATS plugin for WordPress. Learn more about us.